
Default document AI analysis
What AI extracts and verifies automatically on the standard document types
Introduction
AI document analysis verifies uploaded documents automatically. It reads the data they contain, checks that data against rules you configure, and compares it with the data already held in the case.
How the analysis works
- Data extraction: the relevant fields are extracted from the document — name, address, IBAN, registration number and any other information needed for validation.
- Data validation: the extracted data is checked against predefined rules, for example that the document is less than 3 months old.
- Reference data matching: the extracted data is compared with the reference data stored on Dotfile entities (companies, individuals).
Supported documents
- Registration Certificate
- Proof of Address
- IBAN (Bank details)
Enable and configure it
Go to your workspace Settings, then Dotfile AI, to configure each of the document analyses listed above.
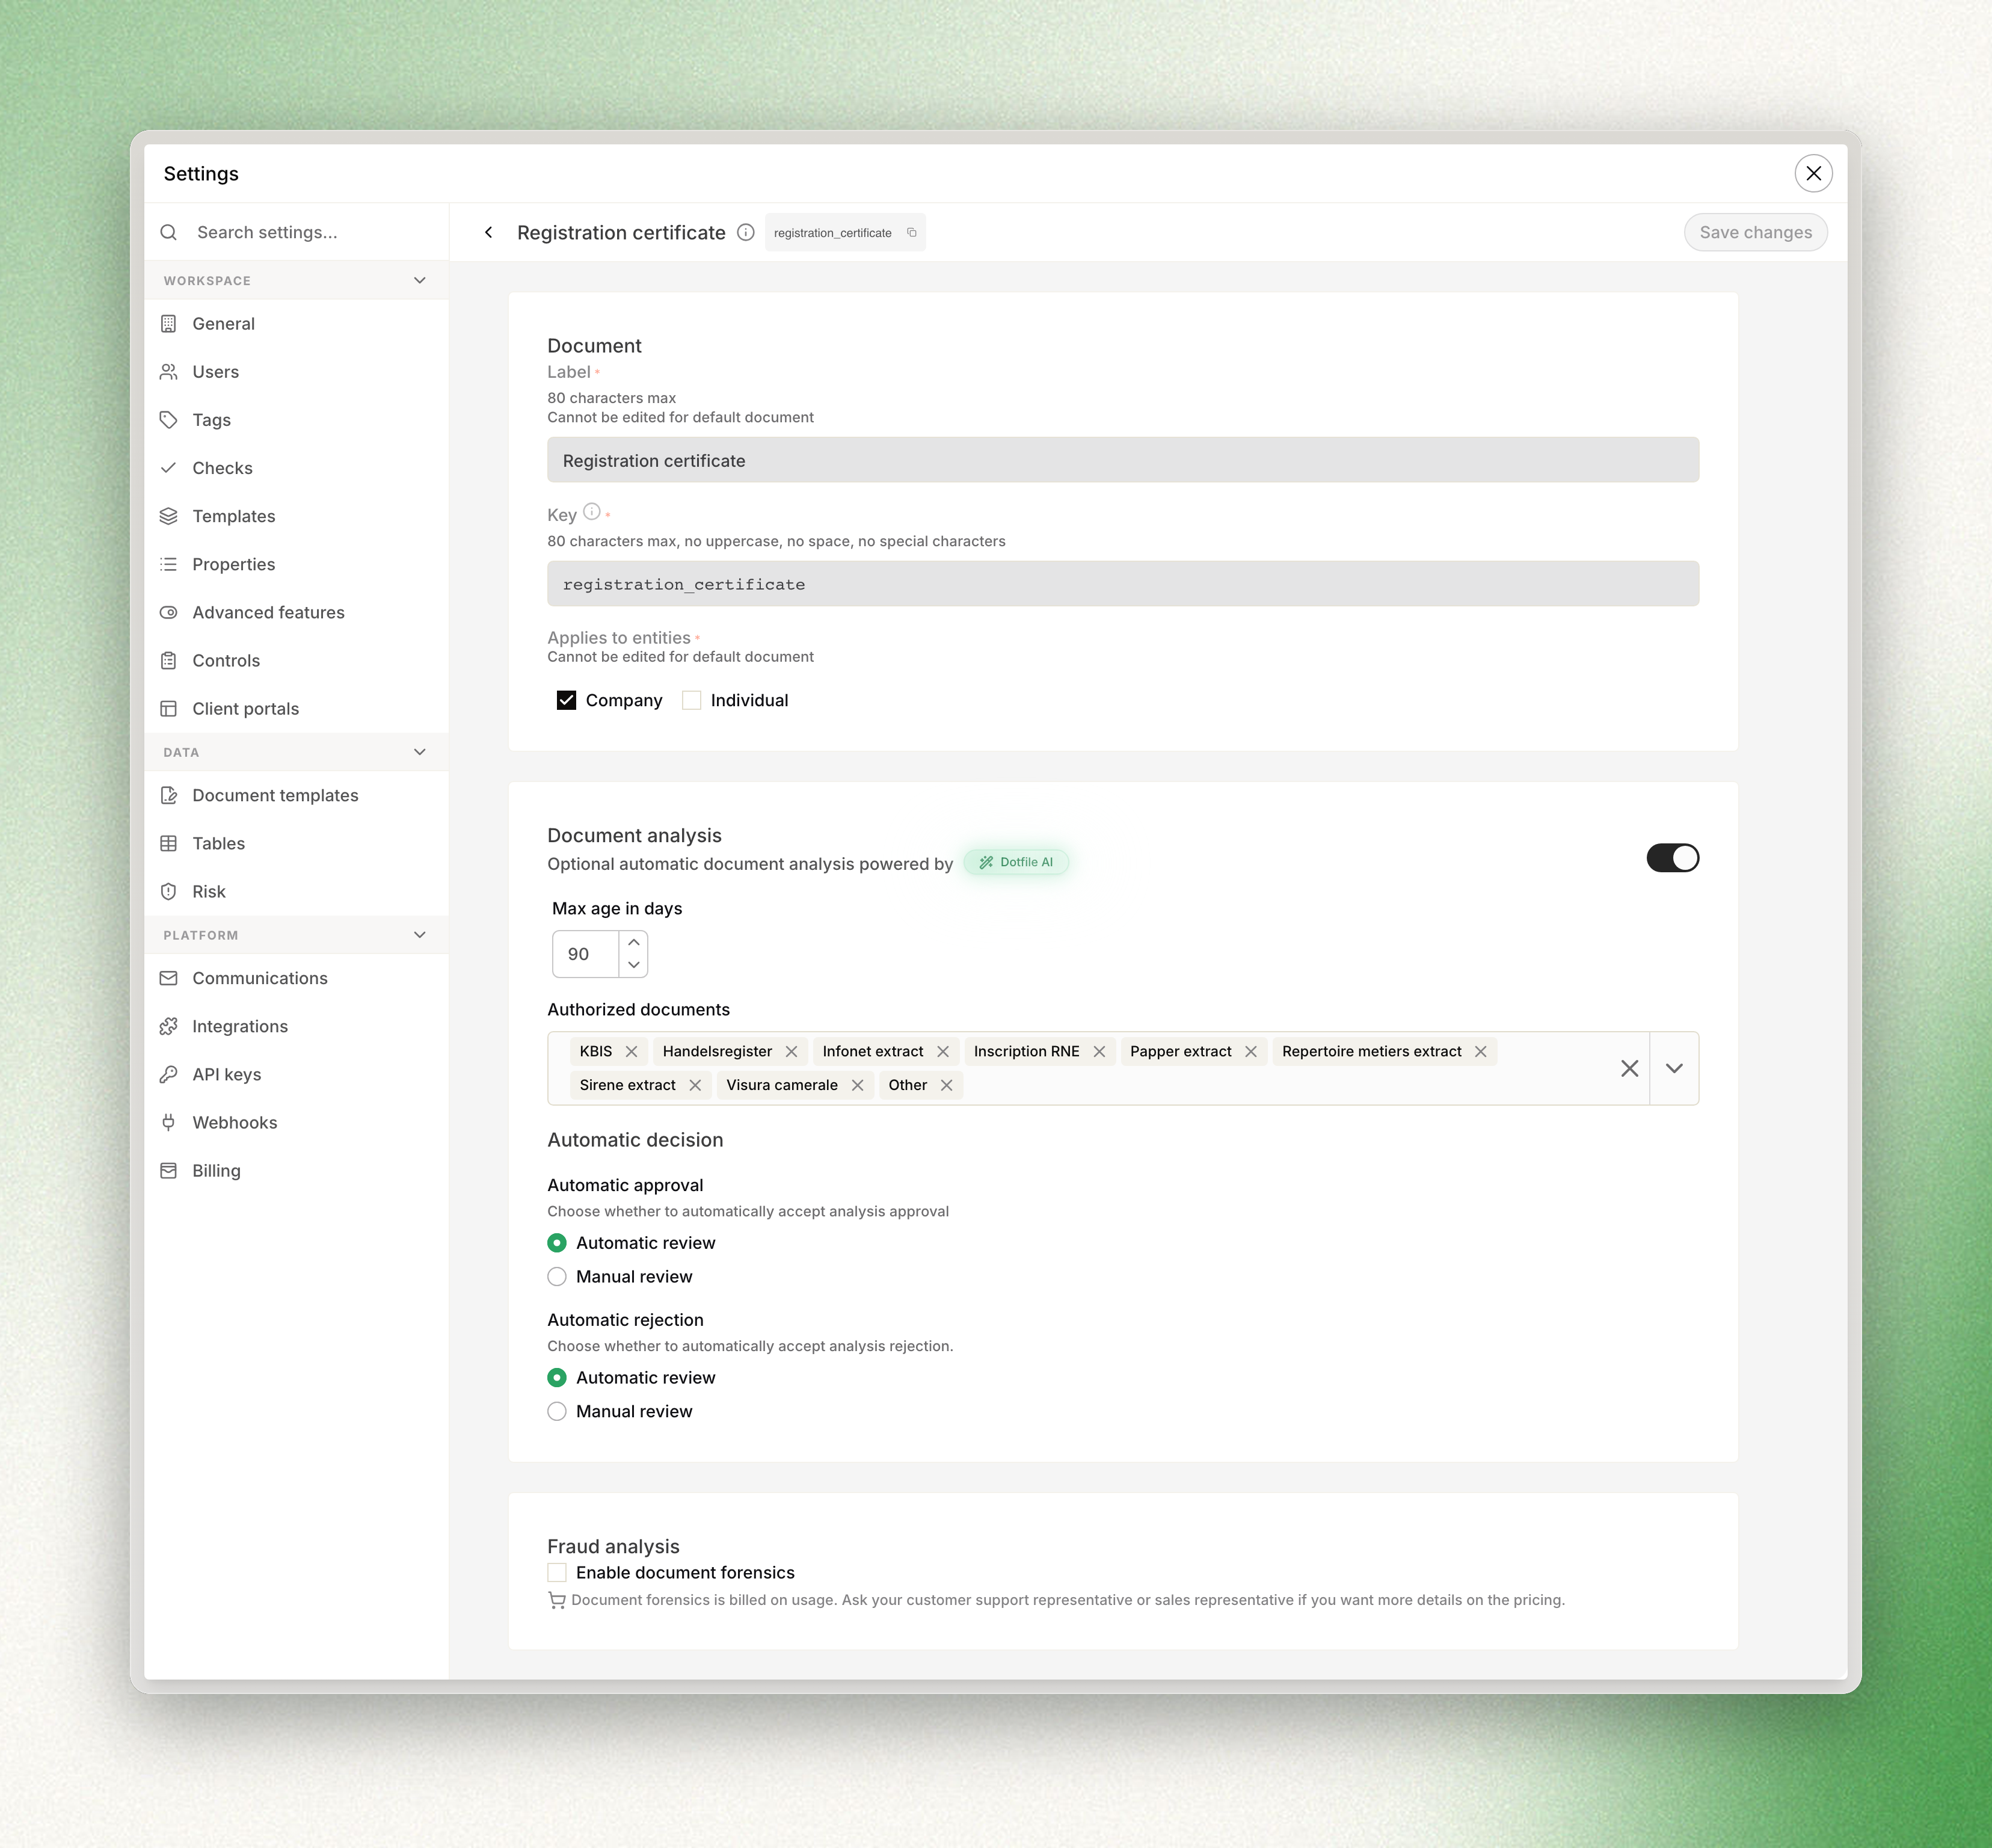
AI document analysis, default or custom, can be added directly to the Onboarding Flow or used through our API. More information about the configuration is available here.
If you need help setting it up, or want to automate the analysis of other document types, contact your Customer Success Manager or [email protected].
Where you see the results
In the console
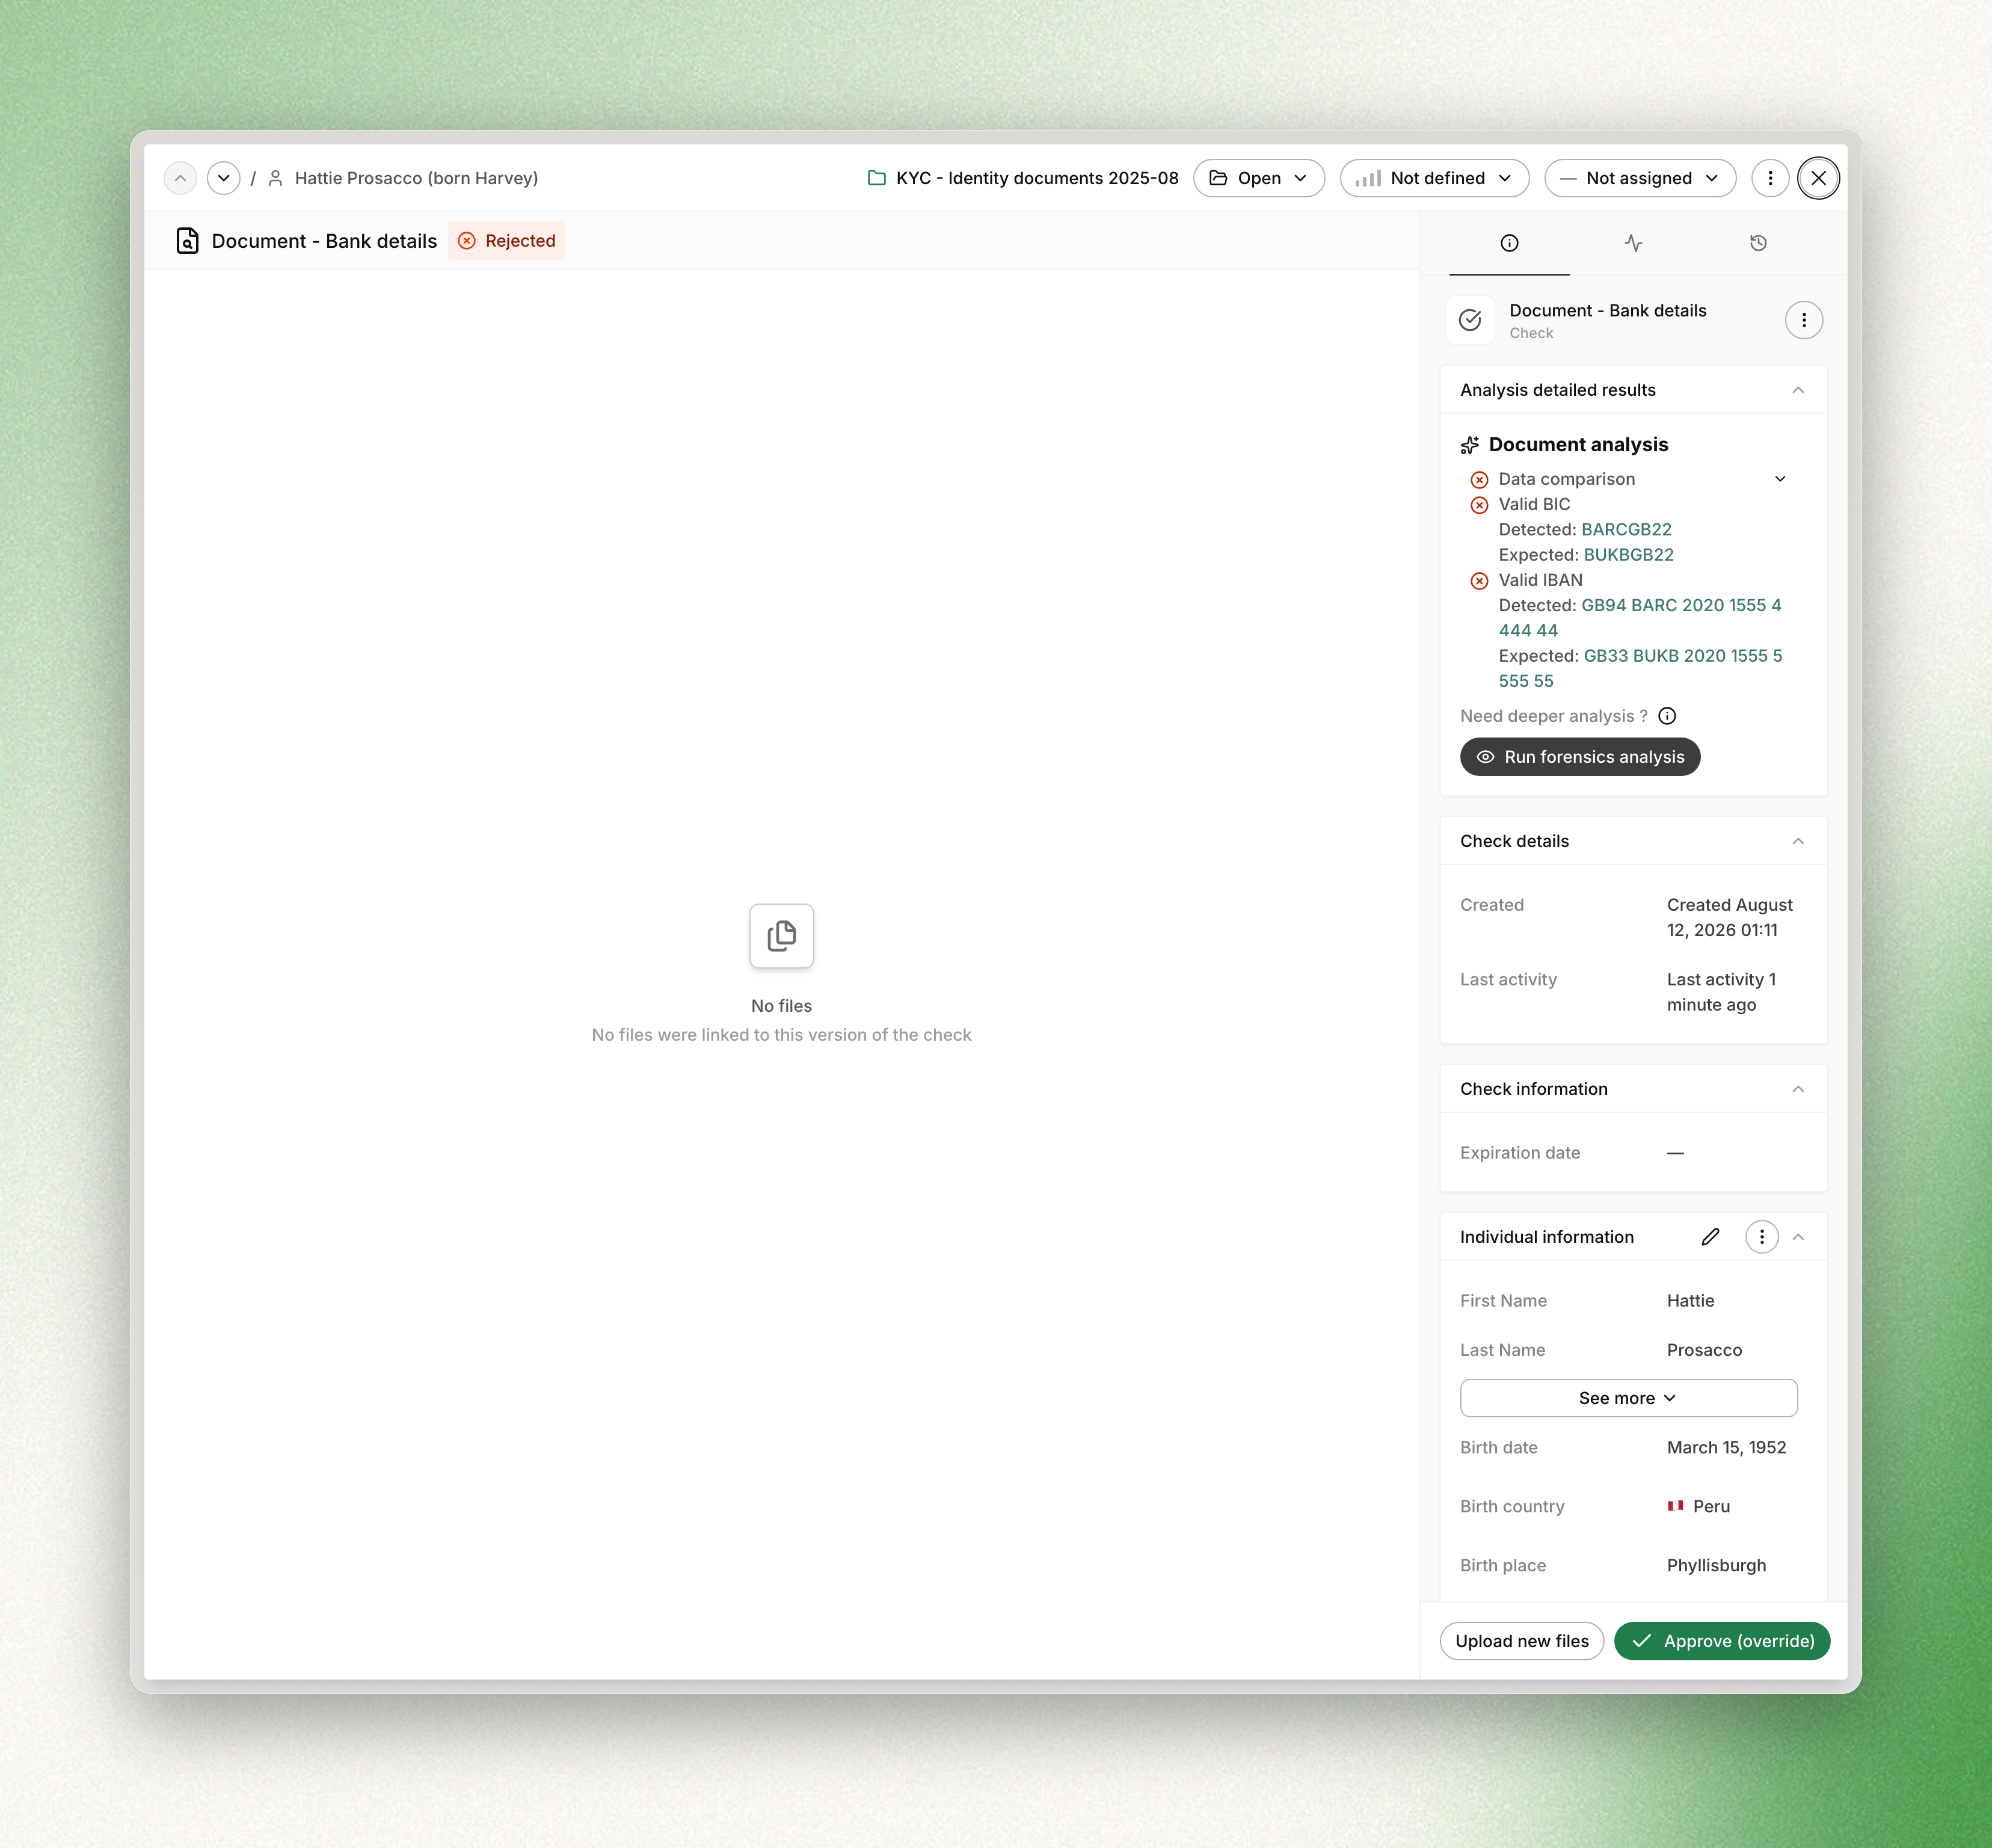
A negative result from automatic document analysis
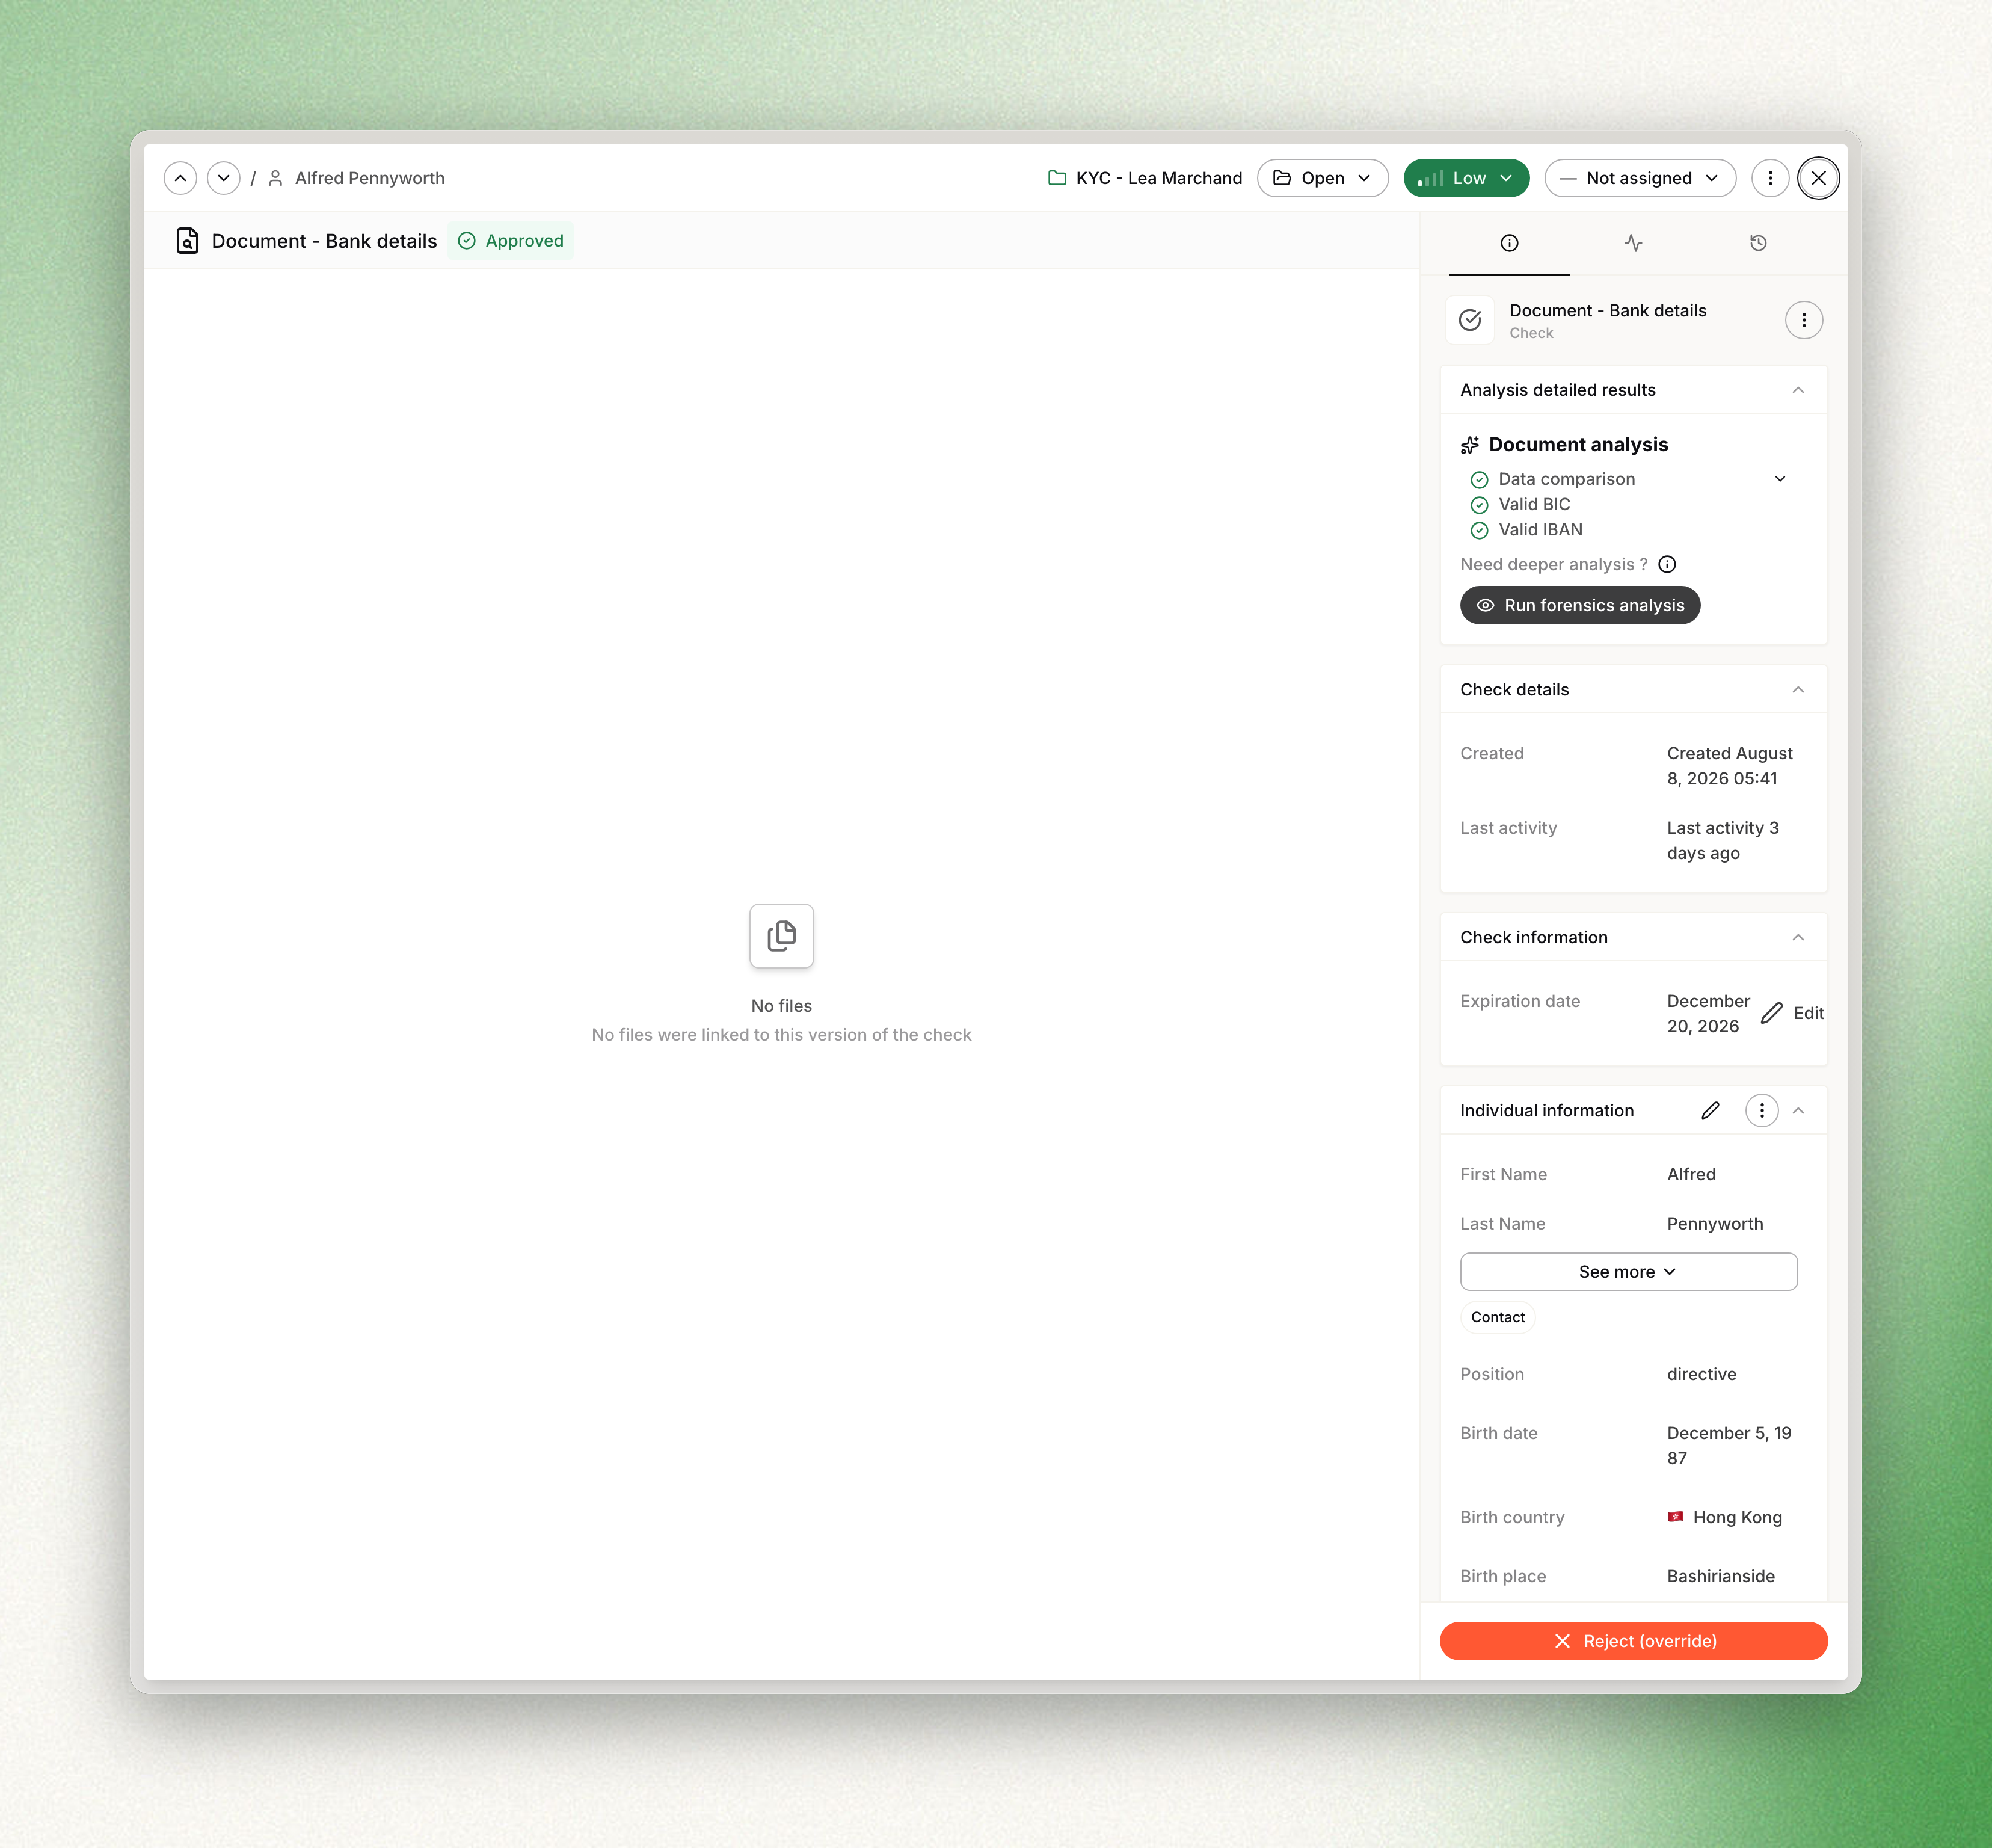
A positive result from automatic document analysis
In the Client Portal
Most frequently asked questions
Who are your LLM providers?
➡️ Dotfile partners with OpenAI and Mistral AI. You can choose your preferred provider.Where are the documents stored, depending on the provider?
➡️ Documents are stored exclusively in AWS S3 (EU), whichever LLM provider you choose.Are uploaded files used to train the model?
➡️ Documents go through OCR with AWS Textract, which never stores them. The extracted raw text is then sent to the LLM provider through its API for processing, and no data is retained there. Uploaded data is never used to train any model.
Updated about 1 month ago